Swap Actor, Edit One Row: 93,000-Word Novel Becomes a 2-Hour Film
"Swap actor, edit one row"—that's the most counterintuitive promise in the CloudKude system, yet it genuinely operates behind the two-hour-and-twenty-minute finished film of *First Avenue*. The original novel is 93,000 words, adapted into 69 chapters and 1,029 shots, completed start to finish by one person on three computers in eleven days. In a traditional film workflow, replacing the lead actor means reshoots, re-editing, re-scoring—at least several weeks and a team of a dozen or more. But in this system, an actor is just one record in the `dbvideo_roles` table: modify the fields related to that character's appearance, then re-trigger the image-generation tasks for all shots involving that character; everything else stays untouched. This works not because of AI's flexibility, but because the entire creative pipeline has been decomposed into an enumerable, re-runnable, replaceable record structure—no implicit coupling exists between layers, and adjusting data at one node doesn't ripple into others. This post is about the core logic of that engineering decomposition.
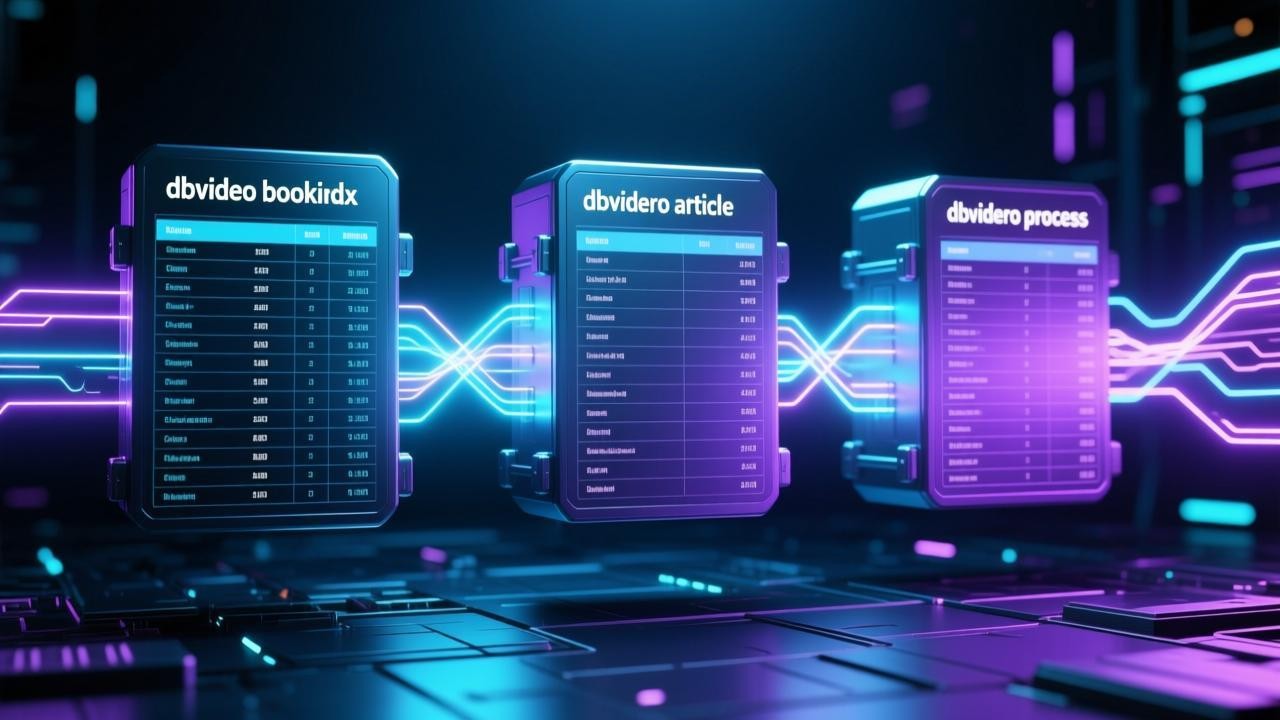
The first layer follows the order: name, then body, then storyboard—corresponding to "one begets two, two begets three, three begets all things." The name is established in `dbvideo_bookidx`: after entering the book title *First Avenue*, a `bookcode` is generated. This `bookcode` is the root node of the entire cinematic universe—it contains no specific content, just a unique identifier, but every downstream table carries this field to mark ownership. The body is established in `dbvideo_article`: the 93,000 words are entered article by article, one row per chapter, forming the complete textual body of the novel. The storyboards are established in `dbvideo_process`: processed chapter by chapter by the `funx.atctoscene` function, which automatically extracts characters and locations from the text, writes them into `dbvideo_roles` and `dbvideo_places` respectively, then generates storyboard records based on character-location combinations. Throughout the process, each layer is an independent table record: `dbvideo_bookidx` has one row representing the book, `dbvideo_article` has 69 rows representing chapters, and `dbvideo_process` has 1,029 rows representing shots. The core significance of this decomposition is that you don't need to revise the entire novel to adjust one shot, and you don't need to rewrite an article to replace an actor. If the dialogue in shot 103 needs changing, you only modify one passage in the corresponding chapter of `dbvideo_article`, then re-run `atctoscene`—only the storyboards under that chapter get refreshed, leaving the 500-plus shots across the other 68 chapters completely unaffected. That's the essence of enumerability: every detail maps to a unique record, with no gray areas.
The core formula of the second layer is scene equals character plus location—this is the underlying principle of storyboard generation. `funx.atctoscene` doesn't generate storyboards directly; it first splits out people and places, then lets the two collide. Suppose a chapter of *First Avenue* depicts the Crown Prince conversing with a priest in Dragon Flag Hall. The system parses out the character "Crown Prince" and the location "Dragon Flag Hall"; these two records enter the character table and location table respectively, then the system creates a new record in the process table specifying that this shot consists of Crown Prince plus Dragon Flag Hall. The key point here is that the character table and location table are maintained independently—they don't exist because of shots; they exist before shots, and shots are merely references and combinations of the two. Therefore, the operation logic behind "swap actor, edit one row" is: you modify the Crown Prince's description in `dbvideo_roles`—say, changing his face from sharp-featured to round and kind—and every shot referencing that character record will automatically use the new description the next time image-generation tasks execute, with no need to adjust shot by shot. The reason a single-row edit doesn't trigger cascading failures is that character and location records are stored in the database first, while storyboard records only retain character IDs and location IDs. These IDs are stable reference relationships that don't invalidate when specific descriptions change; you're changing the attribute values of the referenced record, not the reference itself. Likewise, when a location's lighting style shifts from dusk to midnight, the `imgstyle` field in that `dbvideo_places` row updates, and every shot involving that location gains a midnight atmosphere upon regeneration. That's what replaceability means: nothing in the system is a one-of-a-kind hand-drawn artwork; everything is a standardized record with an ID, and replacing it is just overwriting the corresponding row.
The third layer addresses how multi-machine parallel task grabbing compresses eleven days of work into an acceptable range. Individual records exist as rows in the database with no physical dependencies among them, so whether it's single-machine sequential processing or a hundred machines pulling concurrently, it's just a difference in task allocation method. In *First Avenue*'s actual production, three computers ran different processing nodes simultaneously, each running a task poller. When the system generated 1,029 storyboard records, these weren't manually assigned to specific machines—they entered a task pool, and each computer, when idle, proactively pulled the next unprocessed record. Machine A grabs shot 103, first calls `atctoscene` to confirm the character and location for that shot are ready, then calls `drawrole` to generate the character image, then `placeaiwords` for the scene image, and finally generates the first and last frames and triggers image-to-video. Throughout this, machines B and C neither know nor care, because each is processing different shots. This parallel model works precisely because all input data for each shot lives in independent rows—character, location, and style fields are all sub-queries or direct value references, with no shared global intermediate state requiring lock protection. After swapping an actor, old storyboard records don't need re-running, and already-generated videos don't need redoing—those are marked as completed and are no longer grabbable from the task pool; only records demoted to pending status get re-pulled by the machines. The resulting efficiency gain isn't linear—it's an order-of-magnitude leap. A single machine serially processing 1,029 shots might take over forty days; three machines grabbing in parallel compresses the total timeline to eleven days.
In this structure, 93,000 words are no longer a book but an index table precise to the character level; 69 chapters are no longer titles but 69 independent processing units; 1,029 shots are no longer a shot list but 1,029 individually schedulable, re-runnable, replaceable records. When you convert the object of creation from continuous text and imagery into discrete data rows, creation becomes engineering. The core value of engineering is determinism: every task's input and output are clearly defined, and if any step goes wrong, you can re-run just that step without starting over. Even if the entire system adopts a new style field—say, switching the whole film from "xs" realistic to "gz" period costume—you only update `article.atctype`, then batch-reset the status of all storyboards to unprocessed, and the machines automatically regenerate all visual assets with the new style. This process still requires no adjustments to any character or location descriptions, because style is an outer control field—it only affects the generation model's parameters, not the data relationships themselves. Enumerability, re-runnability, and replaceability interlock into a closed loop, allowing one person plus three computers to outperform, in efficiency, a traditional twenty-person crew's month-long schedule. The essential difference between manual creation and engineered creation is that the former spends energy on repetitive labor, while the latter focuses energy on data-relationship design. When *First Avenue* finishes outputting at 2560×1440 resolution, 30 fps, and 7.7 Mbps, what stands at the end of this assembly line is no longer a screenwriter, a director, or an editor—it's a system operator facing not film reels and editing software but spreadsheets of data tables with clear primary and foreign keys. The miracle of "swap actor, edit one row" is, at its core, saying that creation has become a manageable state transition rather than a one-shot irreversible act. This is engineering's greatest gift to creation: making every modification traceable, every shot reproducible, and enabling one person to accomplish what once took an entire team's extreme workload. Between 93,000 words and a two-hour finished film lies no chasm of inspiration and talent, but rather the granularity of record-keeping—when every sentence, every character, every location possesses its own unique data identity, the order-of-magnitude leap in creative efficiency is no longer fantasy, but the inevitable outcome emerging from densely packed fields and records.